AI
Gemini 2.5 Pro vs DeepSeek V3.1: Parameters, Cost, Coding
Gemini 2.5 Pro vs DeepSeek V3.1: 1M vs 128K context, undisclosed vs 671B parameters, real API prices, and how their successors score on DeepSWE.
By Mohamed Ezz CEO & Founder Mar 27, 2025
Gemini 2.5 Pro vs DeepSeek V3.1 comes down to closed versus open: Gemini 2.5 Pro is Google's multimodal model with a 1,048,576 token context window, while DeepSeek V3.1 is an open weights model with 671 billion parameters (37 billion active per token) that you can download under the MIT license.
Both have newer successors in 2026, and the gap has moved. On the DeepSWE coding benchmark, Gemini 3.8 Flash scores 74% against 63% for DeepSeek V4 Pro, while DeepSeek stays cheaper per task, so this guide covers the original pair first and then the 2026 models.
Last updated: October 10, 2026. Specs, prices and benchmark scores checked on official pages that day.
My Main Points:
- Gemini 2.5 Pro is closed and multimodal: it reads audio, images, video, text and PDFs, with a 1,048,576 token input limit.
- DeepSeek V3.1 is open weights under the MIT license, with 671 billion parameters (37 billion active) and a 128K context window.
- Google has never disclosed Gemini 2.5 Pro's parameter count; its technical report only says sparse mixture of experts.
- DeepSeek is far cheaper: $1.98 per million output tokens for V4 Pro off peak, against $10 for Gemini 2.5 Pro.
- On DeepSWE, Gemini 3.8 Flash (74% ±1) clearly beats DeepSeek V4 Pro (63% ±6), with error bars that do not overlap.
Gemini 2.5 Pro vs DeepSeek V3.1: the quick verdict
- Choose Gemini 2.5 Pro for multimodal work (audio, images, video and PDFs), a context window of over one million tokens, and a fully managed Google service.
- Choose DeepSeek V3.1 if you want open weights you can run yourself, strong coding and math at a much lower price, and no vendor lock in.
- Choosing today? Look at the successors: Gemini 3.8 Flash for the best coding results, DeepSeek V4 Pro or V4.1 Flash for the lowest cost.
Gemini 2.5 Pro vs DeepSeek V3.1 specs and parameters
Gemini 2.5 Pro and DeepSeek V3.1 differ most in openness, context size and what they can read, according to Google's model page and DeepSeek's model card.
| Spec | Gemini 2.5 Pro | DeepSeek V3.1 |
|---|---|---|
| Made by | DeepSeek | |
| License | Closed, API only | Open weights, MIT license |
| Parameters | Not disclosed (sparse mixture of experts) | 671B total, 37B active per token |
| Context window | 1,048,576 tokens in, 65,536 out | 128K tokens |
| Inputs | Audio, images, video, text, PDF | Text |
| Reasoning | Built in deep reasoning | Thinking and non thinking modes |
| API price per 1M tokens | $1.25 in, $10 out (prompts up to 200K) | Depends on host; DeepSeek's own API now serves V4 |
How many parameters does Gemini 2.5 Pro have?
Google has never disclosed how many parameters Gemini 2.5 Pro has. The Gemini 2.5 technical report only says the Gemini 2.5 models are sparse mixture of experts models with native multimodal support, which means each token activates only part of the network.
Figures like 128 billion parameters circulate on blogs and forums, but none of them come from Google, so treat any exact Gemini 2.5 Pro parameter count as a guess.
How many parameters does DeepSeek V3.1 have?
DeepSeek V3.1 has 671 billion parameters in total, and 37 billion of them are active for each token, according to DeepSeek's model card on Hugging Face. It is also a mixture of experts model, and it supports both a thinking mode and a faster non thinking mode.
Gemini 2.5 Pro vs DeepSeek: cost per million tokens
DeepSeek is far cheaper than Gemini 2.5 Pro. Gemini 2.5 Pro costs $1.25 per million input tokens and $10 per million output tokens for prompts up to 200,000 tokens, rising to $2.50 and $15 above that, per Google's pricing page.
DeepSeek V3.1 itself is open weights, so its cost depends on where you run it. DeepSeek's own API has moved on to the V4 family, priced with cheaper off peak and pricier peak rates, per DeepSeek's pricing page.
| Model | Input per 1M tokens | Output per 1M tokens |
|---|---|---|
| Gemini 2.5 Pro | $1.25 | $10.00 |
| Gemini 3.1 Pro (preview) | $2.00 | $12.00 |
| Gemini 3.8 Flash | $0.75 ($1.50 from January 1, 2027) | $3.75 ($7.50 from January 1, 2027) |
| DeepSeek V4 Pro | $0.66 off peak, $1.32 peak | $1.98 off peak, $3.96 peak |
| DeepSeek V4.1 Flash | $0.15 off peak, $0.30 peak | $0.60 off peak, $1.20 peak |
Gemini prices are for prompts up to 200,000 tokens, and DeepSeek input prices are cache miss rates. At off peak rates, DeepSeek V4 Pro output costs about a fifth of Gemini 2.5 Pro output.
Gemini vs DeepSeek for coding
For coding, the fair comparison today is between the newest Gemini and DeepSeek models, because DeepSWE, the coding benchmark we trust most, tracks current releases. DeepSWE is built from tasks written from scratch, so no model has seen the answers during training.
In daily use, DeepSeek V3.1 earned its reputation as a strong, low cost coding model, while Gemini 2.5 Pro's huge context window made it good at reading a whole codebase in one prompt. Their successors have closed part of that gap, because DeepSeek's V4 models now accept prompts of up to 1M tokens too.
Gemini vs DeepSeek in 2026: the DeepSWE verdict
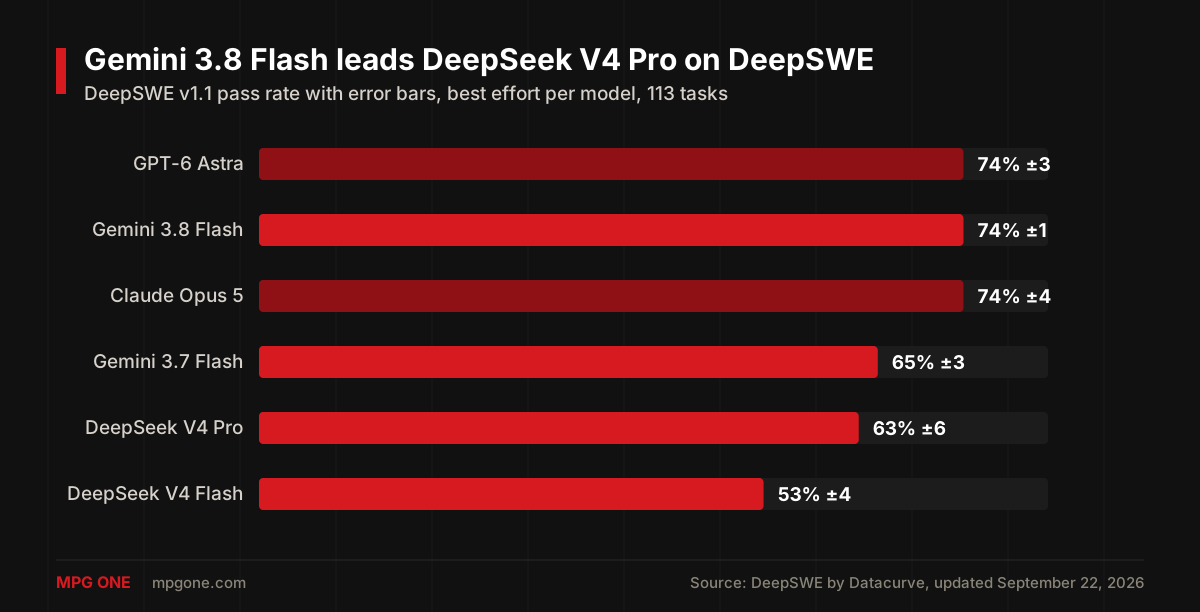
On DeepSWE, Gemini 3.8 Flash scores 74% ±1% and DeepSeek V4 Pro scores 63% ±6%, so Gemini's lead is real: the ranges (73 to 75 against 57 to 69) do not overlap, according to DeepSWE by Datacurve (113 tasks, updated September 22, 2026).
For context, the leaders from other labs sit level with Gemini 3.8 Flash: GPT-6 Astra at 74% ±3% and Claude Opus 5 at 74% ±4%. Gemini 3.7 Flash scores 65% ±3% and DeepSeek V4 Flash 53% ±4%.
DeepSeek wins on cost per task: V4 Flash averages $0.46 and V4 Pro $1.67, against $2.03 for Gemini 3.7 Flash and $2.36 for Gemini 3.8 Flash. GPT-6 Astra costs $4.43 per task and Claude Opus 5 costs $11.84.
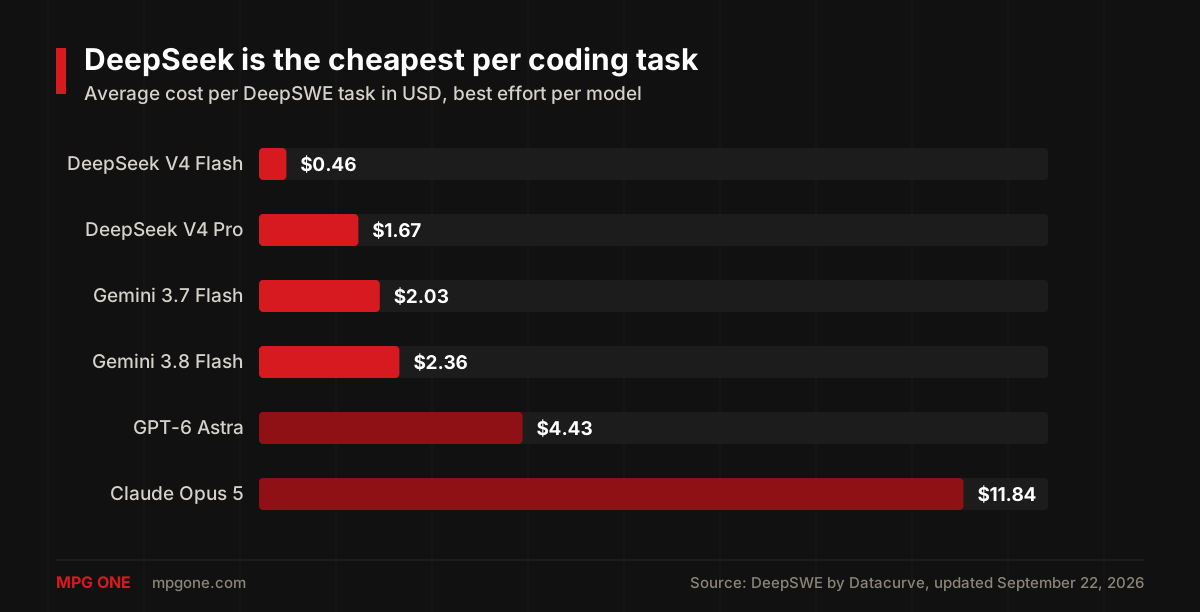
One warning on Gemini 3.8 Flash: Google's price doubles on January 1, 2027, from $0.75 to $1.50 per million input tokens and from $3.75 to $7.50 per million output tokens, so expect its cost per task to rise.
DeepSeek's own two models are harder to separate. V4 Pro's range (57 to 69) and V4 Flash's range (49 to 57) meet at 57, so V4 Flash is the better value unless you need every point of quality.
Secondary sources: other leaderboards
DeepSWE does not include Gemini 3.1 Pro, Google's current Pro model in preview. On the llm-stats.com leaderboard in July 2026, Gemini 3.1 Pro scored 94.3% on GPQA reasoning against 90.1% for DeepSeek V4, and both scored 80.6% on SWE-bench Verified.

Where Gemini wins and where DeepSeek wins
Gemini wins on multimodal input, context size and managed reliability. Gemini 2.5 Pro reads audio, images, video and PDFs and takes over one million tokens in a single prompt, and its successor Gemini 3.8 Flash now also leads DeepSeek on coding.
DeepSeek wins on openness and price. Open weights under the MIT license let you self host, fine tune and inspect DeepSeek V3.1, and DeepSeek's API costs a fraction of Gemini's. If your data cannot leave your own servers, DeepSeek is the only one of the two you can run yourself.
Gemini 2.5 Pro or DeepSeek: which should you choose?
| If you need | Choose |
|---|---|
| To run the model on your own servers | DeepSeek V3.1 (open weights) |
| The lowest price per token | DeepSeek V4.1 Flash |
| The best coding results today | Gemini 3.8 Flash |
| Audio, image, video or PDF understanding | Gemini 2.5 Pro or newer |
| No vendor lock in | DeepSeek V3.1 |
| Managed uptime and Google Cloud integration | Gemini |
Both labs ship quickly, but the core tradeoff, Gemini's managed multimodal power against DeepSeek's open weights efficiency, has held across every release. For the wider field see Claude 4 vs Gemini 2.5 and our GPT-5 accuracy test.
For today's models, see our tested comparisons of Kimi K3 vs Opus 5, the same open weights versus premium tradeoff with 2026 models, and Claude Opus 5 vs Fable 5.
If you're choosing a model to build into your own product, our AI development services team can test the options on your real workload.
FAQ
How many parameters does Gemini 2.5 Pro have?
Google has never disclosed how many parameters Gemini 2.5 Pro has. Its technical report only says the Gemini 2.5 models are sparse mixture of experts models, so figures like 128 billion that circulate online are unofficial guesses.
Is DeepSeek V3.1 open source?
DeepSeek V3.1 is open weights under the MIT license, so you can download it from Hugging Face, run it yourself and use it commercially. It has 671 billion parameters, with 37 billion active per token.
Which is cheaper, Gemini 2.5 Pro or DeepSeek?
DeepSeek is cheaper. Gemini 2.5 Pro costs $1.25 per million input tokens and $10 per million output tokens, while DeepSeek's current V4 Pro costs $0.66 and $1.98 at off peak rates on DeepSeek's own API.
Is Gemini or DeepSeek better for coding?
On DeepSWE, Google's Gemini 3.8 Flash scores 74% against 63% for DeepSeek V4 Pro, and the error bars do not overlap, so Gemini is clearly ahead. DeepSeek still costs less per task: $1.67 against $2.36.
Can I still use Gemini 2.5 Pro?
Yes. Gemini 2.5 Pro is still listed in Google's Gemini API at $1.25 per million input tokens. Google's newest Pro model, Gemini 3.1 Pro, is in preview at $2 per million input tokens.
Related
Helpful next steps
Turn the idea into something useful
When this topic becomes part of a real website, workflow, campaign, or AI system, these MPG ONE pages are the natural places to continue.
Build private AI assistants, workflow automation, knowledge systems, and reporting layers.
Generative AI development servicesBuild generative AI workflows for content, documents, knowledge, and brand-safe operations.
AI agent development servicesDesign tool-using AI agents with memory, retrieval, permissions, and human review.
Custom AI solutionsCreate a custom AI system around your data, tools, permissions, and operating model.
MPG ONE coursesLearn practical AI systems, SEO growth workflows, and talent brand operations with MPG ONE training.