AI
Is ChatGPT Accurate? What OpenAI's Own Error Data Shows
Is ChatGPT accurate? On OpenAI's own hard fact tests, 5.4% of GPT-6 answers had an error, versus 10.5% for the free tier's GPT-5.6 Luna. How to check.
By Mohamed Ezz CEO & Founder Apr 17, 2026
Is ChatGPT accurate? Mostly, but not enough to skip checking: in OpenAI's own October 2026 tests on hard, fact heavy questions, 5.4% of GPT-6 answers contained at least one factual error, and so did 10.5% of answers from GPT-5.6 Luna, the free tier's model. OpenAI picked those prompts because they are hard, and it says the results do not show how often errors happen in everyday use.
After nearly 20 years in AI development and digital marketing, I have watched ChatGPT go from a novelty that made up citations to a tool my team uses every day. This post shows you what OpenAI's own error data says, where ChatGPT still gets things wrong, and how to check an answer before you rely on it.
My Main Points:
- GPT-6 Sol, the model behind GPT-6 in ChatGPT, had at least one factual error in 5.4% of responses to OpenAI's factuality heavy prompts and in 4.1% of responses to its high stakes prompts.
- GPT-5.6 Luna, the default for Free and Go users, erred on 10.5% of the factuality heavy prompts and 8.6% of the high stakes ones, so free answers erred about twice as often as GPT-6 answers.
- GPT-5.5 Instant was at 17.9% and GPT-5.3 Instant at 25.3% on the same factuality heavy prompts, so the error rate has dropped with every release.
- On prompts that users had flagged as past failures, GPT-6 Sol still produced an error 13.5% of the time.
- OpenAI said on August 6, 2026 that responses with errors were about 68% less common with GPT-5.6 Sol than with GPT-5.5 Instant.
- Whatever model you use, verify facts, citations and numbers before you act on them. ChatGPT states wrong answers in the same confident tone as right ones.
In this guide, I'll show you exactly where ChatGPT fails, how the current models compare, and a quick routine for checking answers. Our earlier GPT-5 accuracy test covers the previous generation if you want to see how far things have moved.
ChatGPT Accuracy Rate in OpenAI's October 2026 Data
ChatGPT's accuracy rate now has numbers from OpenAI itself. In its October 2026 update on GPT-6 Sol and GPT-6 Luna, OpenAI reports the share of responses that contained at least one factual error on a set of factuality heavy prompts: 25.3% for GPT-5.3 Instant, 17.9% for GPT-5.5 Instant, 10.5% for GPT-5.6 Luna, 6.6% for GPT-5.6 Sol, 5.6% for GPT-6 Luna and 5.4% for GPT-6 Sol.
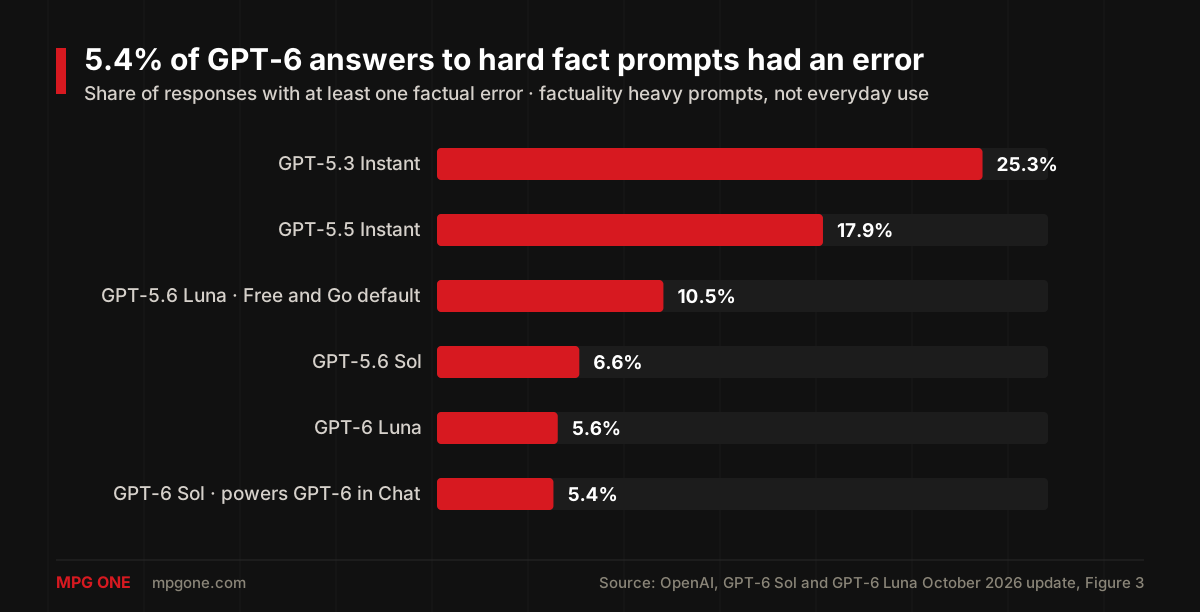
The two highlighted models are the ones you actually get. According to OpenAI's help center, GPT-6 is rolling out as the default in Chat for eligible Plus, Pro, Business and Enterprise users, with GPT-6 Sol powering GPT-6 at every level from Instant to Extra High (Pro plans use GPT-6 Astra). GPT-5.6 Luna powers the default ChatGPT experience for Free and Go users as it rolls out. On this test, a free answer was about twice as likely to contain an error as a paid one.
The high stakes prompts show the same order. GPT-5.3 Instant erred on 36.4% of them, GPT-5.5 Instant on 19.9%, GPT-5.6 Luna on 8.6%, GPT-5.6 Sol on 6.3%, GPT-6 Luna on 4.5% and GPT-6 Sol on 4.1%. The hardest set is the one OpenAI built from prompts users had flagged as past failures: there GPT-6 Sol still produced an error 13.5% of the time, GPT-5.6 Luna 33.5% and GPT-5.3 Instant 61.3%.
Counted by individual claims rather than whole responses, the rates are lower. On the factuality heavy prompts, 1.9% of GPT-6 Sol's claims had an error, against 7.4% for GPT-5.3 Instant, which suggests a failing answer usually has a wrong detail or two inside otherwise correct text.
Two caveats come from OpenAI itself. The prompts were carefully selected to be factuality heavy, previous failures, or high stakes scenarios, and OpenAI states that the values "do not reflect production prevalence". The grading was done by a language model with web access, not by human fact checkers. Treat these numbers as a stress test. The share of everyday answers that go wrong is probably lower, and OpenAI has not published it.
The direction matches what OpenAI reported earlier in the year. In its August 6, 2026 note on improving GPT-5.6 Sol, OpenAI said responses with errors were about 68% less common with GPT-5.6 Sol and about 62% less common with GPT-5.6 Luna than with GPT-5.5 Instant, measured on financial, medical and legal questions.
What ChatGPT Accuracy Means
ChatGPT accuracy means how often the tool gives correct, verifiable information in response to a prompt. When someone asks "is ChatGPT accurate?" they really want to know whether they can trust what it tells them, and the answer affects real decisions every day.
Definition and Concepts
Accuracy in AI is a layered idea. There are a few ways to think about it:
- Factual accuracy: Does ChatGPT give you information that is true and verifiable?
- Contextual accuracy: Does it understand what you are asking and respond in the right context?
- Consistency: Does it give the same correct answer when asked the same question in different ways?
- Source reliability: Is the information it draws from trustworthy in the first place?
ChatGPT is a large language model (LLM). Unless a search or browsing tool is switched on, it does not look things up the way you would Google something. It generates responses from patterns it learned during training on huge amounts of text, so it predicts what a helpful, accurate answer should look like. Most of the time that works. Sometimes it does not.
OpenAI's own guidance on whether ChatGPT tells the truth says the model can make mistakes, misremember facts, or present outdated information with full confidence. That confident tone when the answer is wrong is what catches most users off guard.
Researchers call this a hallucination: text that sounds reasonable and well structured but is factually incorrect. ChatGPT might invent a citation, get a date wrong, or describe a process inaccurately while sounding sure of itself.
Why does this happen? A few reasons:
- Training data limitations: The model learned from text written by humans, and humans make mistakes too.
- Knowledge cutoffs: ChatGPT's training has a cutoff date, so it does not know about later events unless it searches or you tell it.
- No true understanding: It processes language statistically and does not "understand" facts the way a human expert does.
- Ambiguous prompts: If your question is vague, the model may fill the gaps with plausible sounding but incorrect details.
People use ChatGPT for medical questions, legal explanations, academic research, business decisions, and learning new skills. In areas like these, even a small share of errors has consequences. A review on ScienceDirect that examined ChatGPT as a source of scientific information in endodontic local anesthesia makes the point for medicine: in specialized fields, its reliability varies, and professionals need to check its output carefully.
Historical Context
ChatGPT did not arrive fully formed, and knowing where it came from explains both its strengths and its limits today. OpenAI released the original GPT (Generative Pretrained Transformer) model in 2018. It was impressive for its time, but responses were often repetitive, factually loose, and easy to trip up. ChatGPT launched publicly in late 2022 on GPT-3.5, and the world took notice: sign ups took off within days, and so did the first wave of accuracy complaints. Early users found that it would fabricate academic papers, misquote public figures, and get basic math wrong. Those failures came from how the model was built, so no quick patch could remove them.
Here is a simplified timeline of how ChatGPT's accuracy has evolved, with the error rates OpenAI published in October 2026 where they exist:
| Model Version | Release Period | Notable Accuracy Changes |
|---|---|---|
| GPT-3.5 | Late 2022 | Strong language fluency, frequent hallucinations, invented 39.6% of references in a 2024 JMIR test |
| GPT-4 | Early 2023 | Better reasoning, fewer factual errors, invented 28.6% of references in the same test |
| GPT-4o | 2024 | Faster, multimodal, better instruction following |
| GPT-5 family (GPT-5.3 and GPT-5.5 Instant) | 2025 to 2026 | 25.3% and 17.9% of responses with a factual error on OpenAI's factuality heavy prompts |
| GPT-5.6 Luna and GPT-5.6 Sol | 2026 | 10.5% and 6.6% on the same prompts; Luna is now the Free and Go default |
| GPT-6 Luna and GPT-6 Sol | October 2026 | 5.6% and 5.4% on the same prompts; GPT-6 is the default for paid plans |
Each generation brought real gains, and made up references are the clearest example. In a 2024 study in the Journal of Medical Internet Research, researchers asked the models for references to support systematic reviews and then checked whether each paper existed: GPT-3.5 invented 39.6% of its references, GPT-4 invented 28.6%, and Google Bard invented 91.4%. OpenAI has invested in techniques like reinforcement learning from human feedback (RLHF), which trains the model toward answers human reviewers rate as accurate, and it has added web search and retrieval tools so answers depend less on possibly outdated training data.

The core challenge has never fully gone away. The model's design means some uncertainty will always remain in its outputs, and the realistic goal has been to shrink it. What has changed most is user awareness: in 2022 many people treated ChatGPT answers as facts, while today more users know that verification is necessary for anything that matters.
What Drives ChatGPT Accuracy
ChatGPT's accuracy comes from several parts working together, and some push it up while others pull it down. Knowing what they are helps you use ChatGPT smarter.
Main Elements
Training Data
Training data is the foundation. ChatGPT was trained on a massive amount of text: books, websites, articles, and more. Everything it "knows" comes from patterns in that data. If the data had errors, biases, or gaps, those problems can show up in the output.
ChatGPT does not look things up when you ask a question unless search is on. It generates responses from what it learned during training. It is a pattern matching system, and that distinction explains most of its mistakes.
Knowledge Cutoff
ChatGPT's training has a cutoff date, so it does not know about events after a certain point. Ask it about recent news, current prices, or the latest research without search enabled, and it may give you outdated information or, worse, make something up with full confidence. OpenAI's guidance on whether ChatGPT tells the truth says the model is designed to be helpful but is not always right, especially on recent or highly specific topics.
Model Version
Not all versions of ChatGPT are equal, and the gap is large. On OpenAI's October 2026 factuality heavy prompts, GPT-5.3 Instant had an error in 25.3% of responses while GPT-6 Sol had one in 5.4%. Which model you get depends on your plan: Free and Go users are on GPT-5.6 Luna (10.5% on that test) as it rolls out, while Plus, Pro, Business and Enterprise users get GPT-6, according to OpenAI's help center. For how a current OpenAI model compares with a rival, see our tested Fable 5 vs GPT-5.6 Sol comparison.
Prompt Quality
The way you ask a question matters enormously. A vague or poorly worded prompt often leads to a vague or inaccurate answer, and a clear, specific, well structured prompt gives the model more to work with. In my experience working with AI systems, I've seen this play out over and over: the model isn't changing, but the results are completely different based on how you frame the input.
Confidence Without Certainty
ChatGPT sounds confident even when it's wrong. It doesn't flag uncertainty the way a careful human expert would, which is why critical thinking on your end is always part of the equation.
Here's a quick summary of the main elements and how they affect accuracy:
| Component | How It Affects Accuracy |
|---|---|
| Training Data | More accurate data = more reliable outputs |
| Knowledge Cutoff | Older cutoff = higher risk of outdated info |
| Model Version | GPT-6 Sol erred on 5.4% of OpenAI's hard prompts, GPT-5.3 Instant on 25.3% |
| Prompt Quality | Better prompts lead to more focused, accurate responses |
| Hallucination Risk | Model can sound confident while being factually wrong |
Types and Categories
ChatGPT's accuracy varies with the type of task or question you give it, and knowing these categories tells you when to trust it and when to double check.
1. Factual and General Knowledge Questions
For well established facts (historical events, scientific concepts, geography, math) ChatGPT tends to perform well. These topics are heavily represented in its training data, and the information doesn't change often. Even here, errors slip through, so verify anything important.
2. Professional and Technical Topics
ChatGPT can explain medical concepts, legal principles, or engineering ideas at a surface level. When you need precision, it can fall short, and the review on endodontic anesthesia cited above makes the same point: useful overviews, missed clinical nuances. In specialized fields, ChatGPT is a starting point and a qualified professional is the final authority.
3. Creative and Generative Tasks
Writing stories, brainstorming ideas, drafting emails: this is where ChatGPT shines. Accuracy in the traditional sense matters less here, relevance and quality matter more, and the model performs well across versions.
4. Real Time and Current Information
This is ChatGPT's weakest category. Anything that needs up to date data (news, prices, live statistics) is outside its core ability unless search or browsing is on. Without that, it may produce outdated or fabricated answers with full confidence.
5. Reasoning and Logic
Multistep reasoning and complex logic problems are improving with each model, but errors still happen. Word problems, puzzles, and questions with several parts can trip the model up, especially when each step builds on the last.
Here's how accuracy generally stacks up across these categories:
| Task Type | Accuracy Level | Notes |
|---|---|---|
| General Knowledge | Moderate to High | Strong for established facts |
| Professional and Technical | Moderate | Reliable at surface level; deep detail risky |
| Creative Tasks | High | Accuracy less critical here |
| Real Time Information | Low | Needs search or browsing to be useful |
| Reasoning and Logic | Moderate | Improving with newer models |
ChatGPT Accuracy in Real Use
ChatGPT's accuracy in real use is mixed: sometimes impressive, sometimes frustrating. Over the years I've watched businesses, researchers, students, and everyday users put it to work across dozens of fields.
Real World Applications
ChatGPT gets used in a wide range of situations every day. Some play to its strengths; others expose its weaknesses fast.
Content Creation and Writing
Marketers, bloggers, and copywriters use ChatGPT to draft articles, write emails, brainstorm ideas, and edit text. For this kind of work, accuracy matters in a different way than it does for medical or legal content: a travel tips post or a product description doesn't need precise data, and ChatGPT handles these tasks well. It writes clearly, stays on topic, and produces decent first drafts quickly.
It gets tricky when writers ask it for specific statistics, quotes, or citations. ChatGPT can generate numbers that sound real and aren't. If you're writing something that needs verified data, check every figure against a primary source. And if you publish ChatGPT drafts, keep in mind that AI detectors are inconsistent too, as our AI detector accuracy retest found.
Customer Support and Chatbots
Many businesses have built support tools on top of ChatGPT. It can answer common questions, handle basic troubleshooting, and guide users through simple processes. For routine queries (return policies, account setup, product details) it performs well when given accurate source material to work from.
The important words are "given accurate source material." Connected to a company's knowledge base, ChatGPT stays grounded in real information. Left to answer from general training data alone, its risk of wrong answers goes up. That grounding is what our generative AI development services team builds for companies: AI tools that answer from your own verified documents instead of general training data.
Education and Research Assistance
Students use ChatGPT to explain concepts, summarize reading, and help with homework; teachers use it for quiz questions and lesson ideas. For well established concepts (how photosynthesis works, what the French Revolution was about, how to solve a quadratic equation) ChatGPT is generally reliable.
For cutting edge research or niche academic topics, accuracy drops. The model has a knowledge cutoff, and it doesn't always know what it doesn't know, a risky combination in academic settings.
Coding and Technical Help
Developers use ChatGPT constantly to write code, debug errors, explain documentation, and suggest fixes. For common languages and standard tasks it's quite accurate: it can write working Python scripts, explain SQL queries, and catch logical errors in code.
It can also produce code that looks right and has subtle bugs, especially for complex or unusual tasks. Experienced developers test everything it generates. Beginners might not catch the mistakes as easily.
Healthcare Information
This is one of the most sensitive areas. People ask ChatGPT about symptoms, medications, and conditions all the time. OpenAI's own guidance says the model can be helpful but isn't always right, and that users should apply critical thinking when the stakes are high. Medical advice is exactly that kind of situation.
ChatGPT explains general health concepts fairly well. It struggles with nuanced clinical decisions, rare conditions, and current treatment guidelines, and it should never replace a licensed medical professional.
Here's a quick breakdown of how accuracy tends to vary by use case:
| Use Case | Accuracy Level | Key Risk |
|---|---|---|
| General writing and editing | High | Fabricated statistics or citations |
| Customer support (with knowledge base) | High | Outdated or missing information |
| Explaining established concepts | High | Oversimplification |
| Coding assistance | Medium to High | Subtle bugs in complex code |
| Medical and legal information | Medium to Low | Dangerous misinformation |
| Current events and news | Low | Knowledge cutoff, outdated data |
| Niche academic research | Low | Hallucinated references |
Case Studies
Case Study 1: Medical Research Review
Researchers have been studying whether ChatGPT can be a reliable source in clinical settings. One published review examined ChatGPT as a source of scientific information on endodontic local anesthesia, a very specific area of dental medicine. Its finding is a recurring one: ChatGPT gives useful general information, but its reliability for precise clinical guidance is inconsistent and potentially risky. Even in structured, well documented fields, it doesn't always get the details right. For healthcare professionals, that means using it as a starting point and confirming the details elsewhere.
Case Study 2: An Independent Science Test
Washington State University researchers tested consistency as well as accuracy. They gave ChatGPT more than 700 scientific hypotheses and asked it to judge each one true or false, ten times each, as reported by ScienceDaily in March 2026. The free ChatGPT-3.5 answered correctly 76.5% of the time in 2024, and ChatGPT-5 mini reached 80% in 2025. The weak spots were false statements, which it labeled correctly only 16.4% of the time, and consistency: given the identical prompt ten times, it gave consistent answers only about 73% of the time.
Case Study 3: Legal and Financial Queries (Illustrative)
Imagine a small business owner asking ChatGPT about tax deductions or contract clauses. ChatGPT might give a confident, well structured answer based on outdated tax law or a general rule that doesn't apply in their jurisdiction. The response sounds authoritative, the owner trusts it, and that is where problems start. Legal and financial professionals have flagged this pattern repeatedly: ChatGPT presents a partially correct answer in the same tone as a fully correct one. OpenAI's own high stakes test shows the gap is narrowing (GPT-6 Sol erred on 4.1% of those prompts versus 36.4% for GPT-5.3 Instant), but 4.1% is still too many when money or health is involved.
Case Study 4: Everyday Factual Questions
At the other end, ChatGPT handles everyday factual questions well. Ask who wrote Pride and Prejudice, what the capital of Japan is, or how to convert Celsius to Fahrenheit, and it will get these right almost every time. The problems show up when questions get more specific, more recent, or more technical.
What These Examples Tell Us
Across all these applications, a few clear patterns emerge:
- Domain matters. ChatGPT is more accurate in general, well documented areas than in specialized or niche fields.
- Recency matters. Questions about recent events or updated guidelines are more likely to produce errors.
- Stakes matter. The higher the stakes, the more carefully you need to verify what ChatGPT tells you.
- Grounding helps. When ChatGPT is connected to verified, up to date sources, its accuracy improves a lot.
ChatGPT Accuracy Problems and How to Fix Them
ChatGPT's accuracy problems fall into seven groups, and most of them can be managed with the right habits once you know where the cracks are.
Common Challenges
1. Hallucinations, the Biggest Accuracy Problem
ChatGPT can produce responses that sound confident and well structured but contain information that is wrong or made up. It happens because the model generates text from statistical patterns, and it has no separate store of facts to check against.
The problem becomes serious in high stakes fields. The dental review cited earlier found gaps between what the model stated and what peer reviewed research supports. In medicine, law, or any specialized domain, a hallucination can be dangerous.
2. The Knowledge Cutoff Problem
ChatGPT's training data has a cutoff date, so it doesn't know about recent events, newly published research, or updated regulations unless it searches. Ask about something that changed after its training ended and it may give you outdated information without telling you so. It answers a question about current pricing, recent laws, or new medical guidelines with the same confidence it uses for well established facts.
3. Inconsistency Across Sessions and Phrasings
Ask ChatGPT the same question twice and you might get two different answers. Rephrase it slightly and the response can shift in tone, detail, or even factual content. The Washington State University test above measured this directly: consistent answers only about 73% of the time on identical prompts. That makes ChatGPT hard to rely on for tasks that need repeatable outputs, such as product descriptions, legal summaries, or customer answers.
4. Overconfidence in Wrong Answers
ChatGPT rarely says "I'm not sure." It presents uncertain or incorrect information in the same confident tone it uses for things it gets right. As OpenAI's own guidance explains, ChatGPT is designed to be helpful based on patterns in training data, and that design doesn't automatically include knowing when to pump the brakes. This overconfidence misleads users who lack the background to spot errors.
5. Domain Specific Accuracy Gaps
ChatGPT performs well on general topics, writing tasks, and common knowledge, and accuracy drops in narrow or highly technical fields. Here's a general picture of where it tends to struggle most:
| Domain | Accuracy Challenge |
|---|---|
| Medical and clinical | Outdated guidelines, hallucinated citations |
| Legal | Jurisdiction specific nuances, case law errors |
| Financial | Rapidly changing data, regulatory complexity |
| Scientific research | Fabricated studies, misquoted findings |
| Recent news and events | Knowledge cutoff limitations |
OpenAI's own numbers show the same pattern. GPT-6 Sol erred on 5.4% of its general factuality heavy prompts, but on prompts users had flagged as past failures the rate was 13.5%, according to the October 2026 update.
6. Bias in Training Data
ChatGPT learned from a massive amount of internet text, and that text reflects human biases: cultural, political, and social. The model can reproduce those biases in subtle ways, sometimes favoring certain perspectives or framing topics in ways that aren't fully balanced. OpenAI openly describes this as an ongoing area of work.
7. No Real Time Verification
Unlike a search engine, ChatGPT doesn't pull live data from verified sources unless search is on. It generates responses from memory, so to speak. Even when it cites sources, those citations can be fabricated or inaccurate, and the model doesn't check its own work against a live database before responding.
Potential Solutions
Most of these limitations can be managed with the right habits and tools. This is how to get more accurate results from ChatGPT:
Verify Before You Trust
Make it a rule: any factual claim that matters gets checked against a reliable source. This is especially true for medical advice, legal information, statistics, and anything time sensitive. Treat ChatGPT as a starting point, and a trusted source as the final answer.
Use Specific, Detailed Prompts
Vague questions get vague answers. The more context and detail you give, the better the output tends to be. For example:
- Instead of: "What's the best treatment for X?"
- Try: "Based on general medical knowledge up to your training cutoff, what are commonly discussed treatment approaches for X, and what should I verify with a doctor?"
This kind of prompting signals to the model that you want careful, qualified answers.
Ask ChatGPT to Show Its Reasoning
Prompting the model to explain how it arrived at an answer, sometimes called chain of thought prompting, can surface errors before you act on them. If the reasoning doesn't hold up, the answer probably doesn't either.
Turn On Search for Anything Recent
For time sensitive topics, use ChatGPT with search or browsing turned on. This lets it pull current information instead of relying only on training data. It won't remove every error, but it shrinks the knowledge cutoff problem a lot.
Cross Check With Domain Experts
For anything in medicine, law, finance, or science, ChatGPT should be one input among several. Use it to get an overview or to structure your thinking, then validate the specifics with a qualified professional or a peer reviewed source.
Use It for What It Does Best
Play to the model's strengths. ChatGPT is highly accurate for:
- Drafting and editing written content
- Summarizing long documents
- Brainstorming and ideation
- Explaining well established concepts in simple terms
- Writing and debugging code (with human review)
Build Human Review Into Your Workflow
If you're using ChatGPT in a business context, for customer support, content creation, or research, build in a human review step. Don't let AI generated content go out the door without someone checking it, especially anything public facing or legally sensitive. If you take the next step and let an AI agent act on its own, our guide to creating an AI agent shows where human approval belongs.
Where ChatGPT Accuracy Is Heading
ChatGPT's accuracy has improved with every release, and the pace is measurable. On OpenAI's factuality heavy prompts, the share of responses with a factual error fell from 25.3% for GPT-5.3 Instant to 5.4% for GPT-6 Sol, according to the October 2026 update.
Emerging Developments
Real Time Knowledge Access
One of the biggest accuracy problems with ChatGPT has always been its training cutoff. Search is now built into ChatGPT, and when a model pulls live information the accuracy gap shrinks, especially for news, prices, medical updates, and legal changes.
Better Reasoning and Fact Checking
OpenAI has invested heavily in chain of thought reasoning. Instead of jumping straight to an answer, the model works through problems step by step, which already reduces errors in math, logic, and questions with several parts. Future versions will likely take this further and check their own outputs before showing them to you.
Multimodal Accuracy Improvements
ChatGPT can now process images, audio, and documents. As these abilities improve, the model will be able to cross reference text claims against visual data, charts, or uploaded sources. That opens the door to answers grounded in evidence you've provided.
Domain Specific Fine Tuning
General accuracy is one thing. Accuracy in a specific field such as medicine, law, or engineering is another, and research like the endodontic review above keeps finding both strengths and important gaps. This kind of testing is pushing developers to create fine tuned versions of these models. Expect more specialized AI tools trained deeply on one field.
Improved Hallucination Detection
Hallucination, when ChatGPT confidently states something false, is still one of the biggest accuracy concerns. OpenAI and other AI labs are working on systems that flag when a model is uncertain. Future versions will likely show confidence signals or source citations more consistently.
Here's a quick look at how accuracy related features have evolved and where they're heading:
| Feature | Current State | Expected Direction |
|---|---|---|
| Knowledge cutoff | Fixed training date plus optional search | Closer to real time access |
| Hallucination rate | 5.4% of GPT-6 Sol responses on OpenAI's hard prompts | Lower with self checking |
| Domain accuracy | Varies widely by topic | More specialized fine tuned models |
| Source citation | Inconsistent | More consistent and verifiable |
| Confidence signaling | Minimal | Clear uncertainty indicators |
| Reasoning depth | Improved with chain of thought | Deeper, multistep verification |
Predictions
Based on where things stand today and the trajectory I've watched, here is what I expect for ChatGPT's accuracy over the next two to three years.
Accuracy Will Keep Rising and Will Not Reach 100%
As OpenAI notes in its own guidance on what ChatGPT gets right and where it falls short, the model works by pattern recognition, so errors will always be possible. The error rate on OpenAI's hard prompts has fallen with every release, and I expect it to keep falling without ever reaching a point where human review becomes unnecessary.
Verification Will Become a Built In Feature
Right now, verifying ChatGPT's output is your job. I believe that will shift. Future versions will likely include fact checking layers that compare responses against trusted databases or flag claims that can't be verified. That won't remove the need for critical thinking, but it will make the tool more trustworthy by default.
Specialized AI Will Outperform General ChatGPT in Niche Areas
For general questions, ChatGPT will remain a strong tool. For high stakes fields like healthcare, legal research, or financial planning, purpose built AI systems trained on curated, verified industry data will likely outperform it. Think of the difference between a general doctor and a specialist: both matter, and you want the specialist when the stakes are high.
User Behavior Will Evolve
People are already learning to prompt better, cross check outputs, and treat ChatGPT as a starting point. As AI literacy improves, users will get more accurate results, partly because the model improves and partly because people learn to work with it better.
Regulation Will Shape Accuracy Standards
Governments are moving toward requiring AI transparency, especially in healthcare, education, and finance. That pressure will push developers to build more accurate, auditable systems, and accuracy will become a legal requirement in many industries as well as a product feature.
ChatGPT's accuracy will keep improving. The smart approach is still to understand the tool's limits today, use it carefully, and stay informed as it changes.
FAQ
How accurate is ChatGPT?
ChatGPT is accurate most of the time but not all of the time. On OpenAI's own October 2026 tests of hard, fact heavy prompts, 5.4% of GPT-6 responses and 10.5% of GPT-5.6 Luna responses contained at least one factual error. OpenAI chose those prompts because they are difficult, so everyday error rates are likely lower, though it has not published them.
Is ChatGPT 100% accurate?
No. ChatGPT is not 100% accurate on any version. Even GPT-6, the current default for paid plans, produced at least one factual error in 4.1% of OpenAI's high stakes test prompts and 13.5% of prompts that users had previously flagged as failures, according to OpenAI's October 2026 update.
How accurate is ChatGPT as a percentage?
There is no single percentage for ChatGPT accuracy because it depends on the model and the question. On OpenAI's October 2026 hard fact prompts, GPT-6 Sol had no factual error in roughly 19 of every 20 responses (5.4% had one). In an independent Washington State University test reported in March 2026, ChatGPT-5 mini judged scientific hypotheses correctly about 80% of the time but gave consistent answers to identical prompts only about 73% of the time.
Is ChatGPT reliable for facts and citations?
ChatGPT is reliable enough for a first draft of facts, and citations always need checking. A 2024 study in the Journal of Medical Internet Research found that GPT-3.5 invented 39.6% of the references it gave for systematic reviews and GPT-4 invented 28.6%. Newer models do better, but you should still open every source ChatGPT cites before you use it.
Is the free version of ChatGPT less accurate?
Yes, on OpenAI's own tests the free version of ChatGPT is less accurate. Free and Go users get GPT-5.6 Luna, which had a factual error in 10.5% of responses to factuality heavy prompts, while GPT-6 Sol, the model behind GPT-6 for Plus, Pro, Business and Enterprise users, was at 5.4%, about half the rate.
Final Thoughts
ChatGPT is a powerful tool, and it is not perfect. It can answer questions, explain complex topics, and help with many tasks, and it also makes mistakes: outdated information, misstated facts, and confident wrong answers, the problem known as hallucination.
So, is ChatGPT accurate? Mostly, and it depends on what you ask it and which model you're using. On OpenAI's own hard prompts, GPT-6 produced a factual error in about 1 answer in 20 (5.4%), and the free tier's GPT-5.6 Luna in about 1 in 10 (10.5%). For general knowledge and everyday tasks, ChatGPT performs well. For decisions in medicine, law, finance, or science, verify what it tells you.
I use ChatGPT daily in my work at MPG ONE. It saves time and sparks ideas, and I always check important facts before acting on them. That habit has saved me from errors more than once.
Things are improving fast. GPT-6 is now rolling out as the default for Plus, Pro, Business and Enterprise users, retrieval augmented generation (RAG) and built in search already reduce errors, and each release has cut the error rate on OpenAI's hardest prompts. My advice is simple: use ChatGPT, treat it like a smart assistant who sometimes gets things wrong, and verify anything that matters.
If your company needs AI that answers from verified data instead of guesses, our AI development services team builds exactly that.
Helpful next steps
Turn the idea into something useful
When this topic becomes part of a real website, workflow, campaign, or AI system, these MPG ONE pages are the natural places to continue.
Build generative AI workflows for content, documents, knowledge, and brand-safe operations.
AI development servicesBuild private AI assistants, workflow automation, knowledge systems, and reporting layers.
AI agent development servicesDesign tool-using AI agents with memory, retrieval, permissions, and human review.
Custom AI solutionsCreate a custom AI system around your data, tools, permissions, and operating model.
MPG ONE coursesLearn practical AI systems, SEO growth workflows, and talent brand operations with MPG ONE training.